All projects
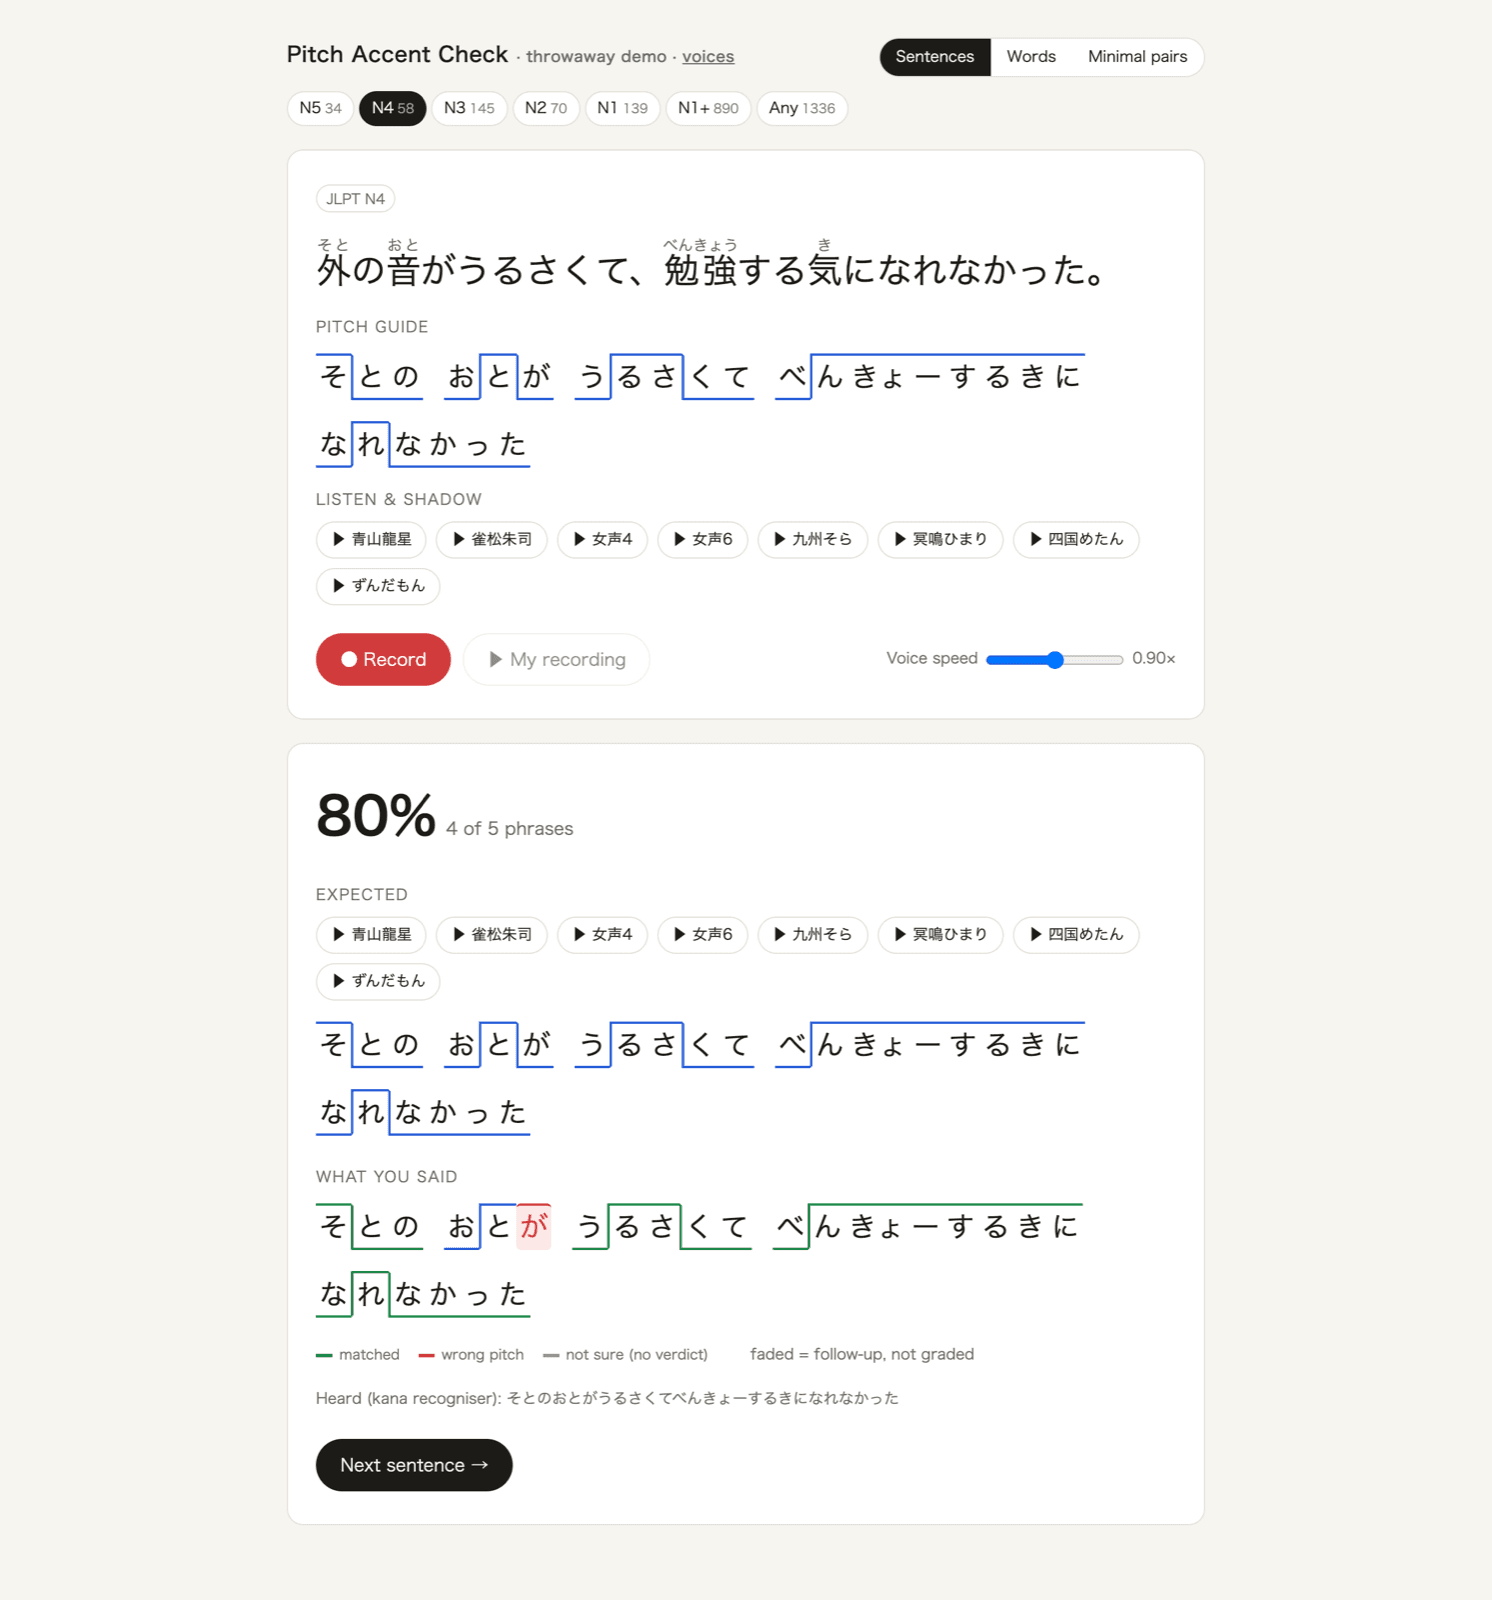
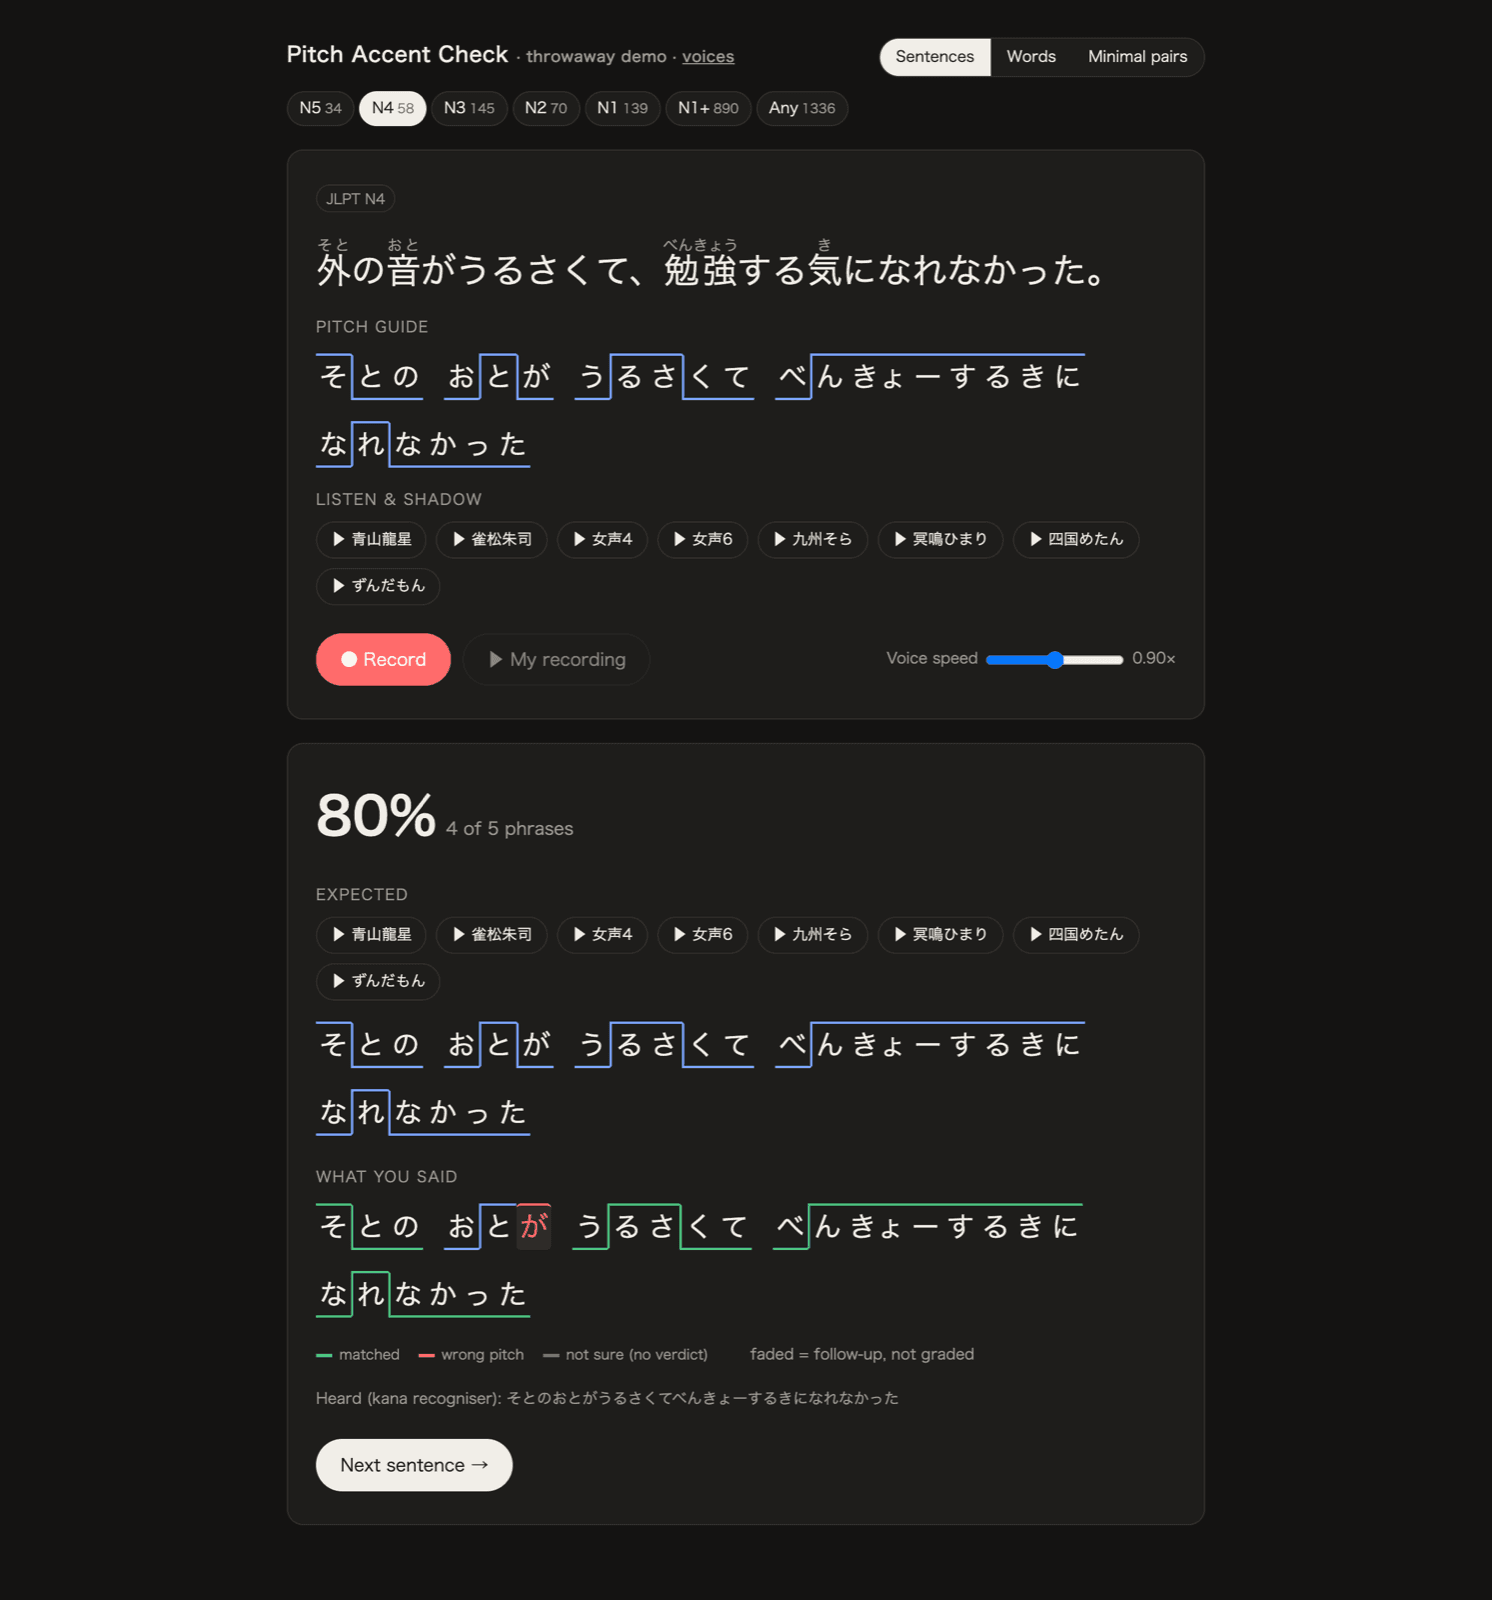
Graded phrase by phrase: here only 音が came out flat instead of dropping. 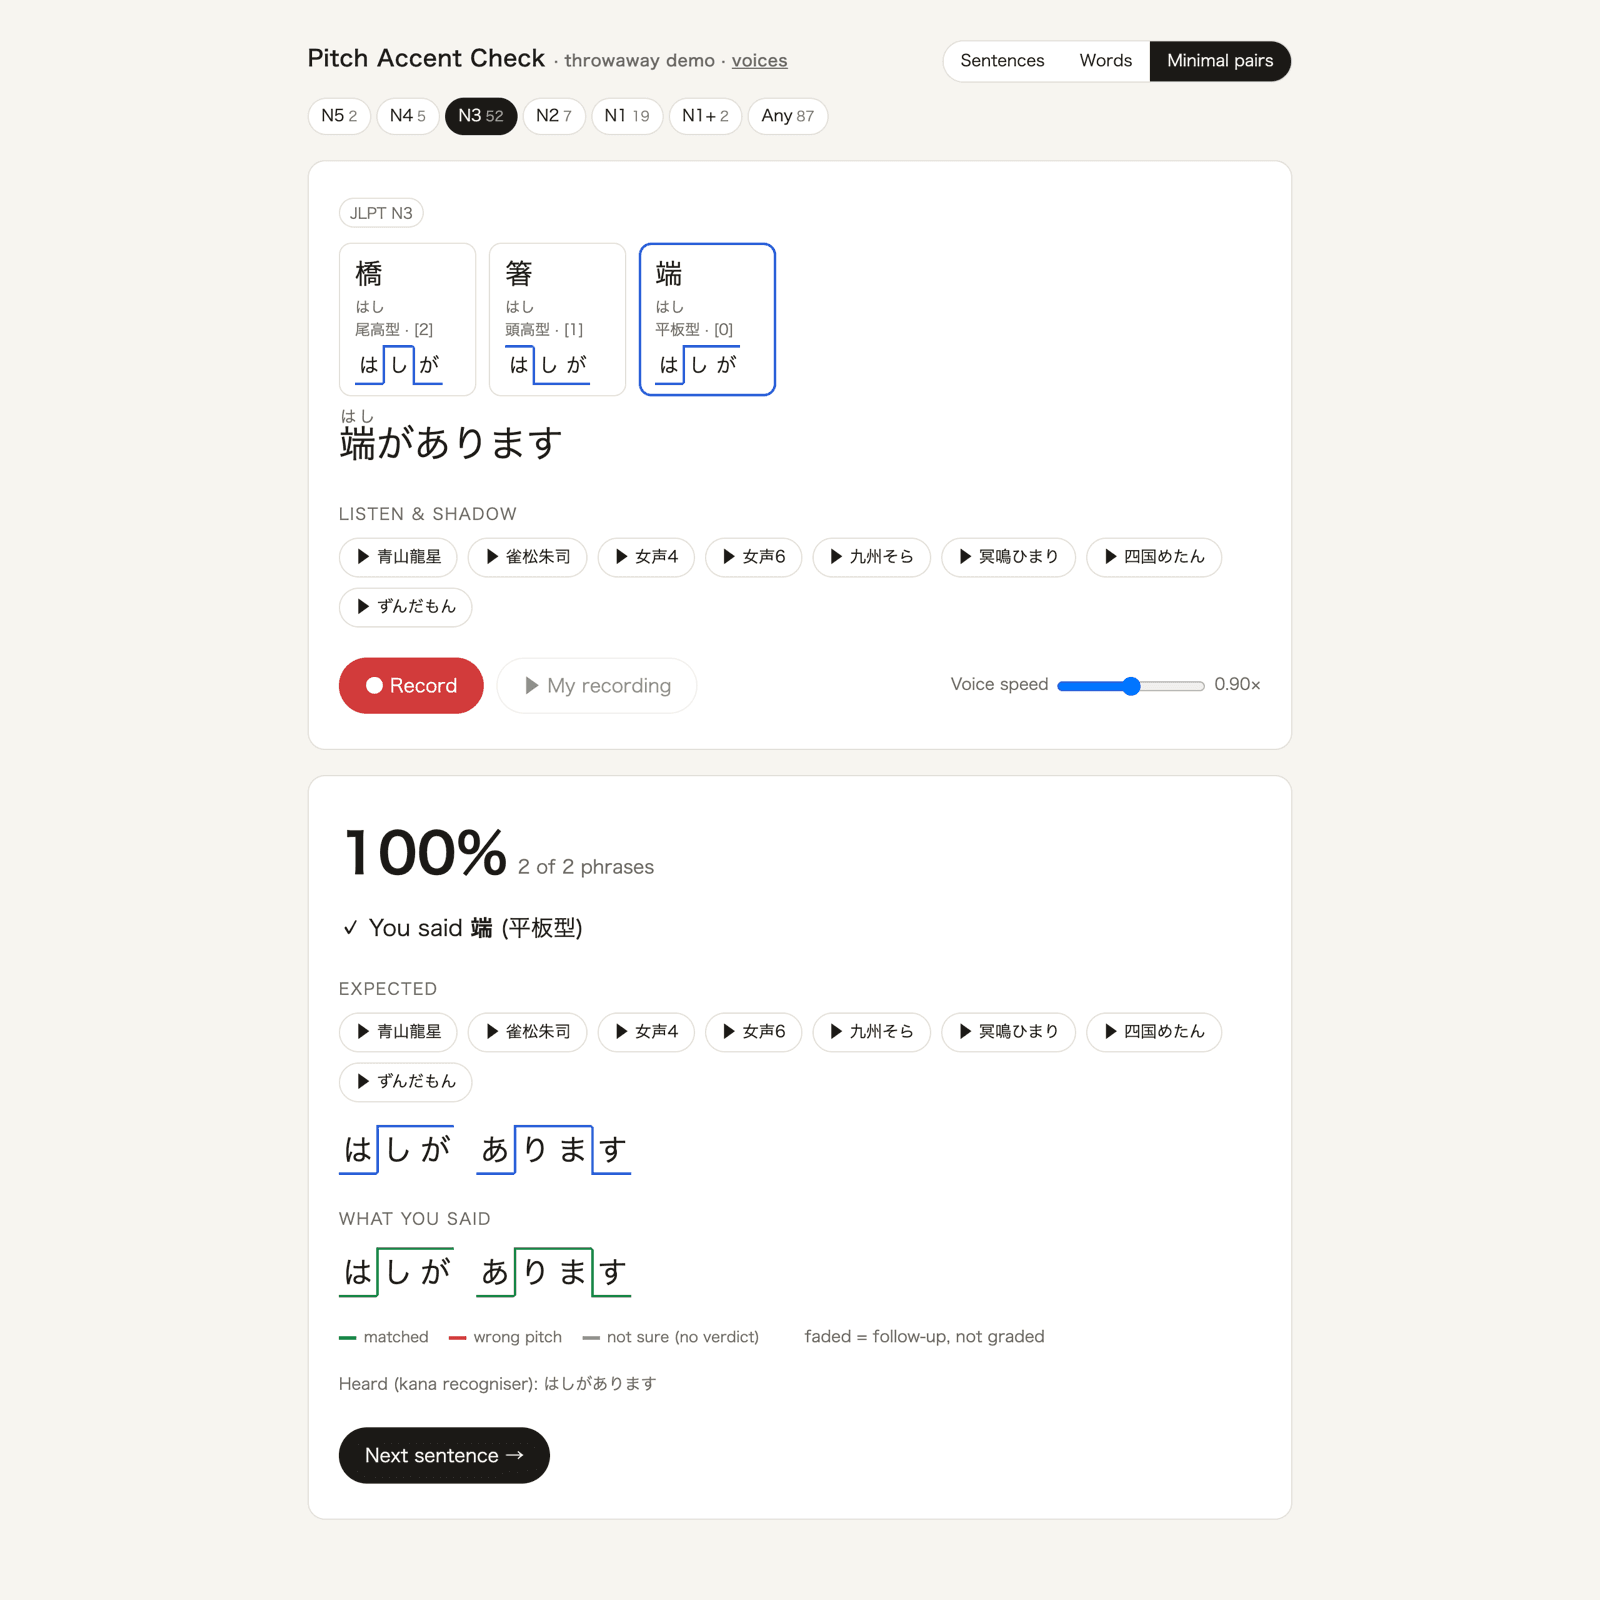
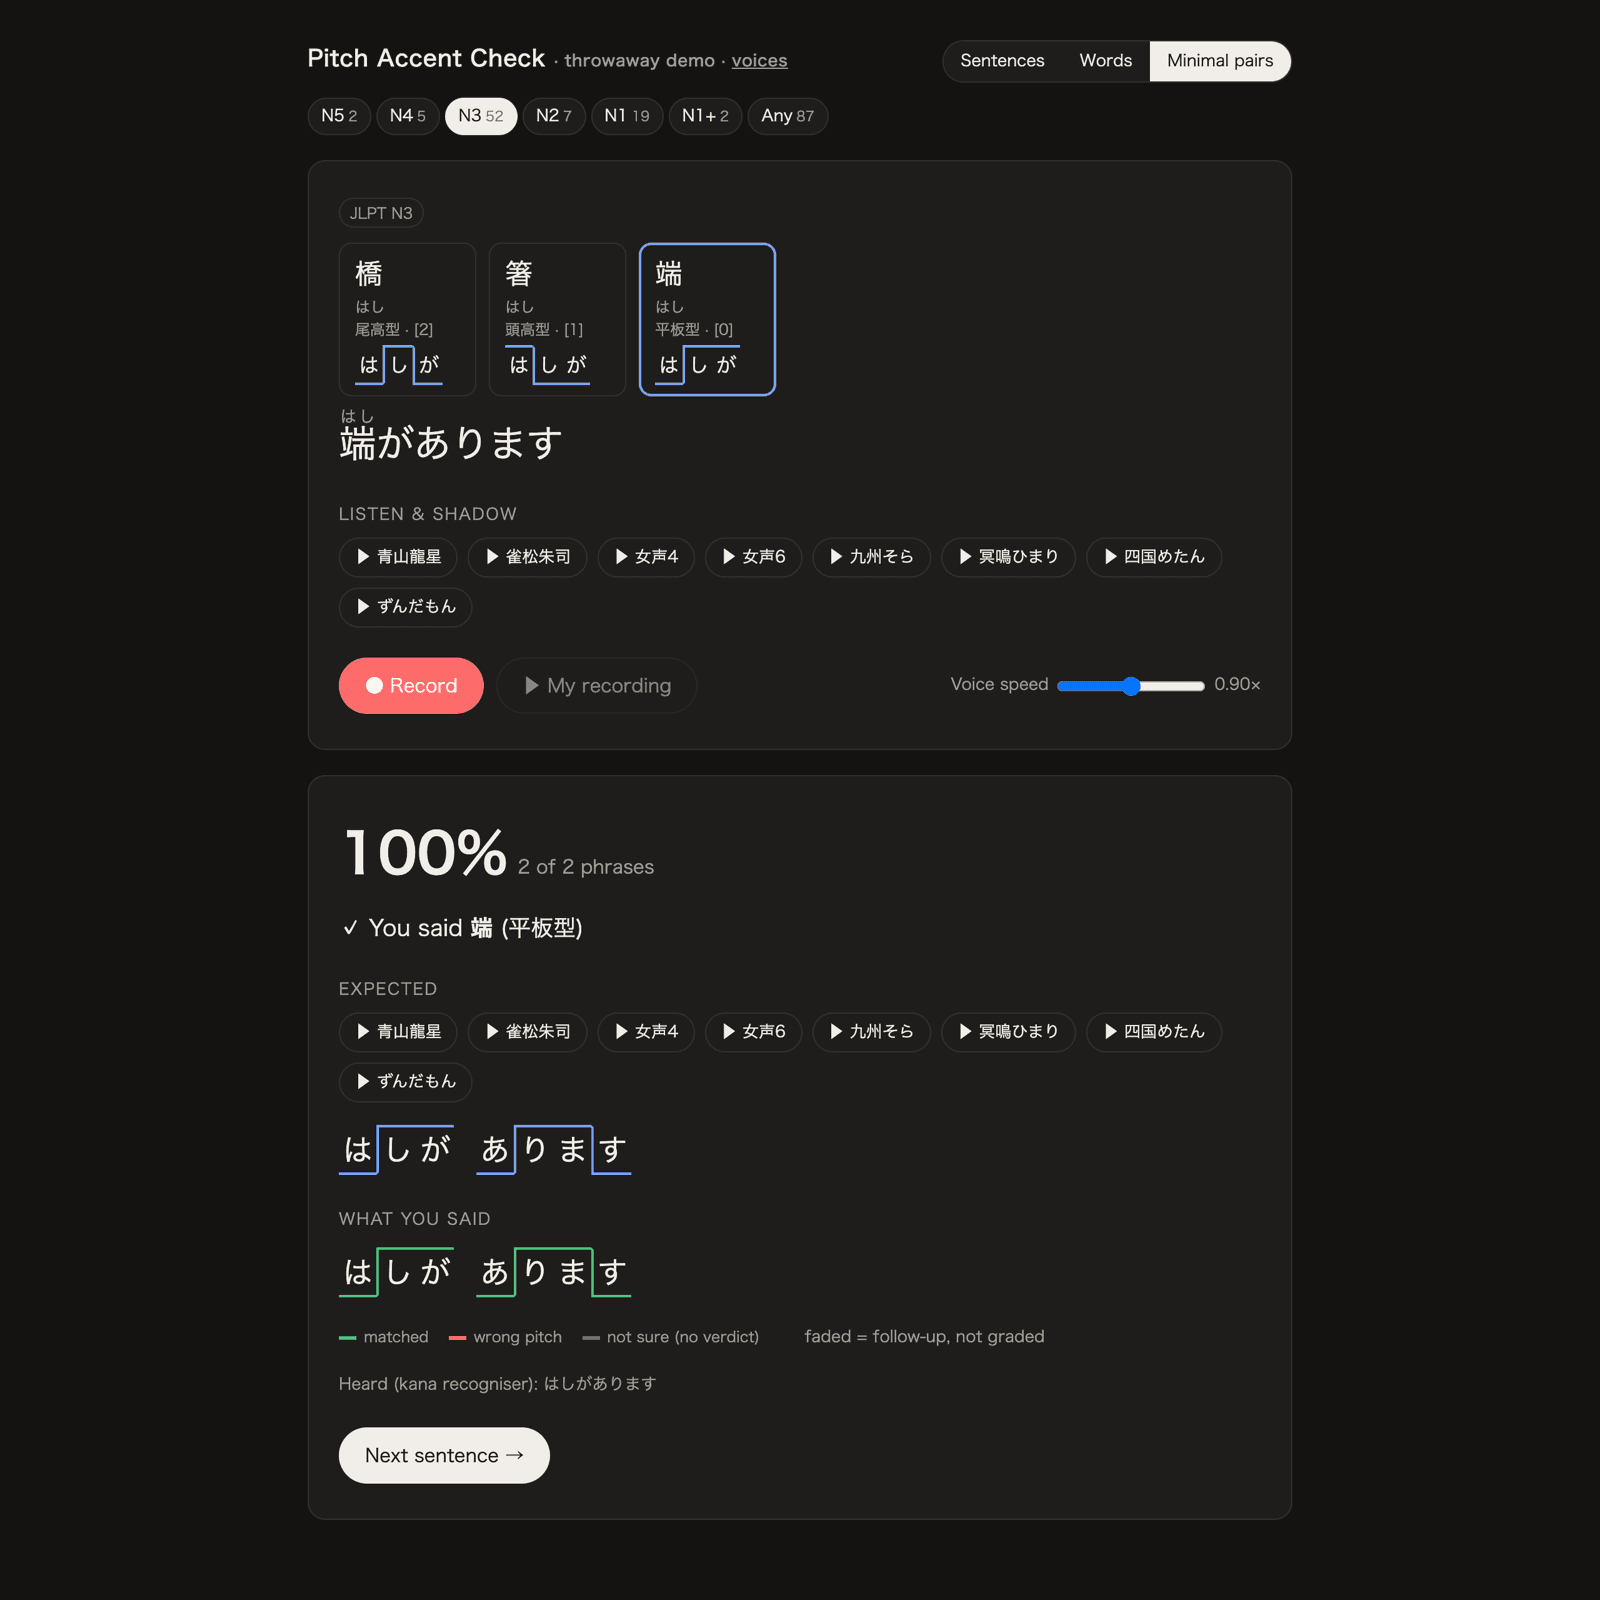
Minimal pairs: which はし did you say?
Kanpeki Pitch
Research prototypeSay a Japanese sentence; see which words had the wrong pitch.
A pitch-accent trainer that runs entirely on-device. It works out the dictionary accent for each phrase, lines your recording up mora by mora, tracks your pitch, and grades every phrase: ok, wrong, or honestly not sure. A research spike toward an iOS app, with a web demo for sentences, JLPT vocabulary and minimal pairs like 箸・橋・端.
View on GitHub ↗Built with
- Python
- PyTorch
- scikit-learn
- FastAPI
- wav2vec2
- OpenJTalk
- VOICEVOX
Highlights
- OpenJTalk for the expected accent, a hiragana wav2vec2 model for mora timing, SwiftF0 for pitch.
- A tree model and a BiGRU sequence model, averaged: calibrated on new speakers, fewer “not sure”s.
- Evaluated on speakers and sentences it never trained on: about 4% false alarms and 1% missed errors.
- It abstains rather than guessing: telling a learner they were wrong when they were right is the worst failure.
- Reference audio from VOICEVOX, reshaped so its pitch matches the dictionary.